Pipeline and codec
compress_bin_to_h5 turns a raw 2500 Hz SpikeGLX LFP binary into an lfpack file in two stages: preprocessing to a 250 Hz float32 array (checkpointed as .npy), then the codec. compress_to_h5 runs the codec alone. Cadzow denoising is on by default with the latest ibl-neuropixel settings; cadzow=False gives pure decimation. The software versions and the settings used are stored in the file (provenance).
Preprocessing
| Step | What | Why |
|---|---|---|
| Saturation | ADC-clipped spans detected on the raw band (amplitude only), stored as an interval table | Found before filtering smears them; muted at the end |
| Bad channels | ibldsp.voltage.detect_bad_channels_cbin (International Brain Laboratory 2022): good, dead, noisy, outside the brain; stored as labels |
Incoherent channels inflate the SVD noise floor |
| Dephasing | NP1 per-channel sub-sample shift (ibldsp.fourier.fshift) |
Aligns the channels’ sampling times |
| Highpass | 0.5 Hz zero-phase Butterworth, recording ends apodised | Removes drift, keeps delta and infra-slow activity |
| Interpolation | Bad channels replaced from their neighbours | |
| CAR | Median across channels subtracted | Common-mode noise |
| Decimation | 2500 → 250 Hz FIR (q=10) |
The LFP band sits well below 125 Hz |
| Cadzow | F-X Cadzow denoising | Removes incoherent channel noise before the SVD |
| Muting | Saturated spans zeroed with a short cosine taper, after Cadzow | Muting earlier leaks energy back through the filters |
F-X Cadzow works frequency bin by frequency bin (up to fmax): the complex channel vector of each spatial window is laid out as a block-Toeplitz matrix over the probe geometry, truncated to a low rank, and averaged back to channels. The settings follow the probe geometry (cadzow_lfp_kwargs): rank=5, niter=1, fmax=None, nswx=64, ovx=32, ppca_k=2.0 with Gavish-Donoho singular-value shrinkage, on the full lateral × depth grid for the NP1 checkerboard (ibldsp.cadzow.LFP_KWARGS_NP1) and on the channels for NP2 (LFP_KWARGS_NP2). They are the default; cadzow_kwargs keys override them. Dead and noisy channels are also passed to Cadzow, which estimates them from its fit (bad_channels_as_missing=True), so they are not interpolated again after it; pass False to interpolate them instead.
Provenance
Every meta group records lfpack_version, ibl_neuropixel_version, lfpack_commit (set when lfpack runs from a git checkout, with a -dirty suffix for uncommitted changes, empty for a regular install) and processing, a JSON string with the Cadzow settings actually used, the decimation factor and the highpass. LFPackReader(...).provenance returns them as a dict:
from lfpack import LFPackReader

LFPackReader("my_recording.lf.h5").provenance
The installed package version is lfpack.__version__. Files written before lfpack 1.2 have none of these attributes (format_version and epsilon / alpha tell the codec format and tier). When the Cadzow checkpoint is reused, its settings are not known and processing["cadzow"] is null.
Codec
The 250 Hz array is cut into 8 s chunks \(X_j\) (2048 samples, coded with 128 guard samples on each side so wavelet edge effects fall outside the written samples).
Spatial stage. Each chunk is factorised \(X_j \approx U_j\,\mathrm{diag}(s_j)\,V_j^\top\) with rank \(r_j = \#\{k : s_k > \varepsilon\,\sigma_0\}\), where \(\sigma_0\) is the median of the lower half of the singular values. At ε = 100 the rank is about 17. The spatial modes of a recording barely move over a session, so the file stores one basis \(B\) (nc × 32) per recording and, per chunk, float16 coefficients \(C_j\) with \(U_j s_j \approx B\,C_j\). This costs < 0.01 dB of SNR and shrinks the spatial part about 20×.
Temporal stage. Each row of \(V_j^\top\) is decomposed into db4 level-5 wavelet packets and hard-thresholded at \(\tau_k = \alpha\,\sigma_0 / s_k\). Every discarded coefficient therefore costs less than \(\alpha\,\sigma_0\) of reconstruction error, whatever the mode, and strong modes keep more temporal detail than weak ones. The dominant row always keeps its floor_k = 64 largest coefficients so a low-SNR chunk never decodes to zero; a muted chunk still decodes to exactly zero.
Choosing ε and α
Measured on 11 IBL NP1 recordings, with behaviour decoding (wheel speed from LFP band power) run on every reconstruction:
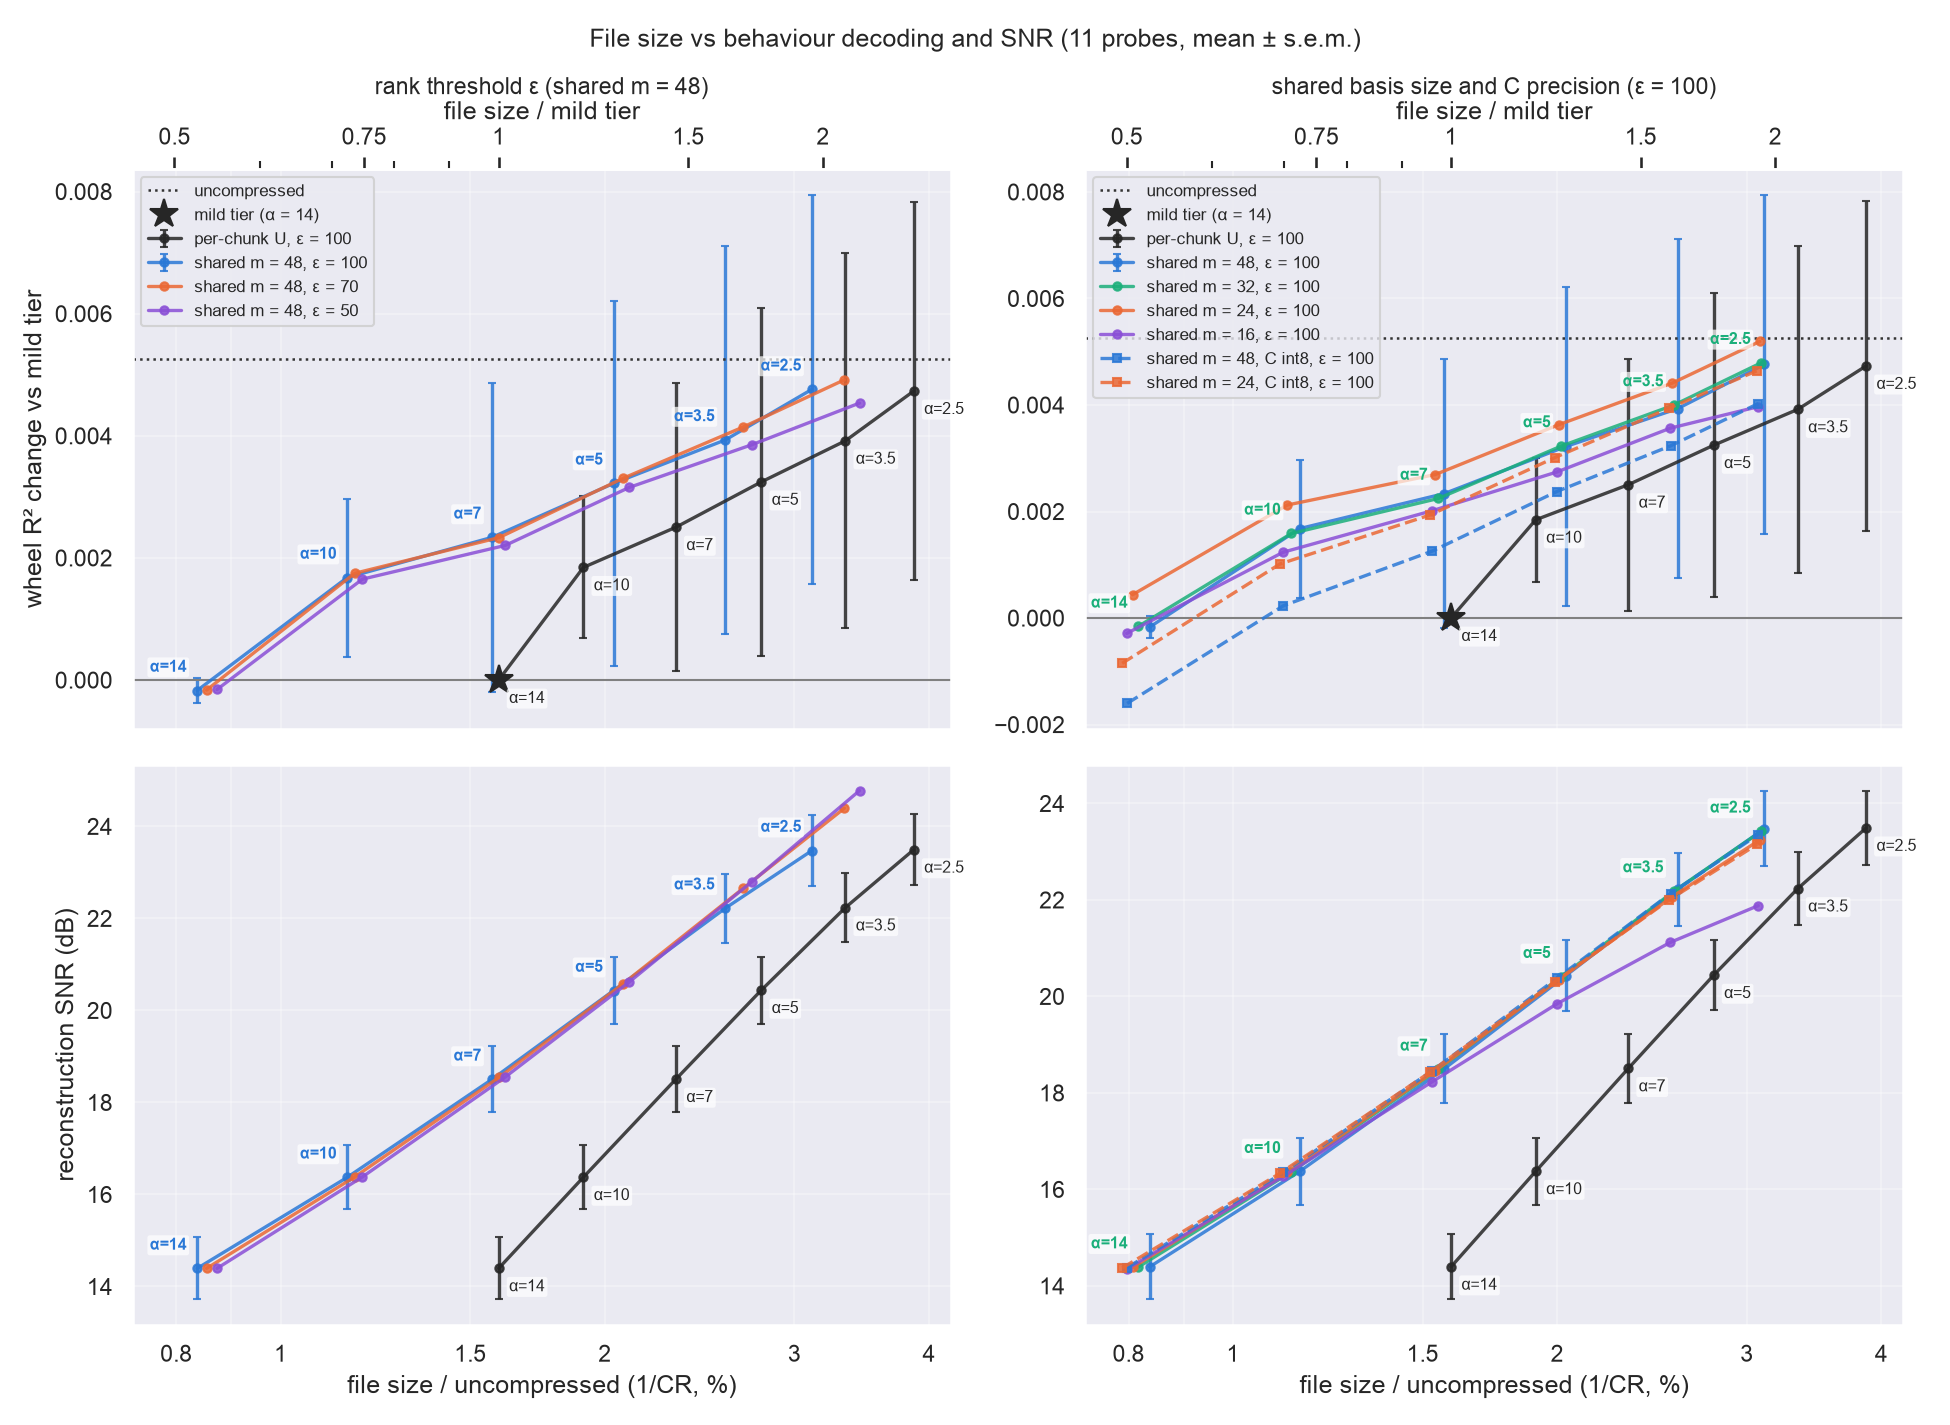
- α sets decoding quality, and nothing else does: at equal α the shared basis and per-chunk U decode identically. The defaults are ε = 100 and α = 7; see the table on the home page for α = 14 and 2.5.
- More rank does not pay: ε = 70 matches ε = 100 and ε = 50 is slightly worse per byte.
- The spatial part is exhausted at m ≈ 24–32 vectors (1–4 % of the file); m = 16 loses up to 1.6 dB.
- Keep the coefficients in float16: int8 saves 1–5 % of the bytes at unchanged SNR but degrades decoding on most recordings. SNR is a poor proxy for decoding.